Academic Research
Here are some highlights of my academic interests. See the complete list of my publications below or on Google Scholar.
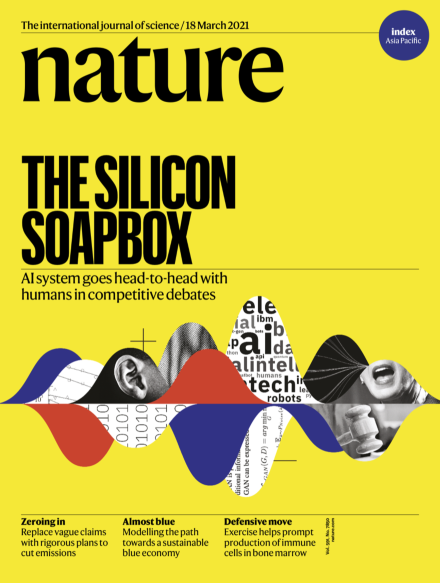
Computational Argumentation and Debating
Research in computational argumentation focuses on understanding and generating arguments, with applications in debating systems and listening comprehension.
Selected Publications
- Noam Slonim et al. An autonomous debating system. Nature 591, 379–384 (2021).
- Shachar Mirkin et al. Listening Comprehension over Argumentative Content. EMNLP 2018.
- Shachar Mirkin et al. A Recorded Debating Dataset. LREC 2018.
Personalized Machine Translation
We proposed personalizing machine translation systems in order to adapt automatic translation systems from 2 different perspectives:
- For Individual users' preferences
- For preserving authors' styles through translation
Selected Publications
- Ella Rabinovich, Shachar Mirkin, Raj Nath Patel, Lucia Specia and Shuly Wintner Personalized Machine Translation Preserving Original Author Traits. EACL 2017.
- Shachar Mirkin and Jean-Luc Meunier. Personalized machine translation: Predicting translational preferences. EMNLP 2015.
- Shachar Mirkin, Scott Nowson, Scott, Caroline Brun, Julien Perez. Motivating Personality-aware Machine Translation. EMNLP 2015.
Model-aware Improvement of Source Translatability
Research in improving source translatability focuses on modifying source texts to enhance translation quality.
Selected Publications
- Shachar Mirkin et al. Confidence-driven Rewriting for Improved Translation. MT Summit 2013.
- Sriram Venkatapathy and Shachar Mirkin. An SMT-driven Authoring Tool. COLING 2012.
Academic Service
Program Committee Member
EMNLP 2026 (Area Chair, ARR) // ACL 2024 (Area Chair, ARR) // W-NUT 2022 // ARR April 2022 / ACL 2022 (ARR) // W-NUT 2021 // EMNLP 2021 // EACL 2021 // COLING 2020 // *SEM 2020 // EMNLP 2020 // ACL 2020 // LREC 2020 // W-NUT 2019 // ACL 2019 // NLP+CSS 2019 // COLING 2018 // ACL 2018 // NAACL 2018 // EMNLP 2017 // *SEM 2017 // ACL 2017 // Journal of Natural Language Engineering (JNLE) 2016 // COLING 2016 // LREC 2016 // EMNLP 2016 // *SEM 2016 // EMNLP 2015 // *SEM 2015 // CICLING 2015 // Journal of Language Resources and Evaluation (LREV) 2014 //EMNLP 2014 // COLING 2014 // WMT 2014 // LREC 2014 // WMT 2013 // Journal of Language Resources and Evaluation (LREV) 2013 // IJCNLP 2013 // *SEM 2013 // Journal of Computer Science and Technology (JCST) 2013 // WMT 2012 // EACL 2012 // LREC 2012 // ACM TIST Journal, Special Issue on Paraphrasing 2011 // EMNLP 2011 // TextInfer 2011 // COLING 2010 // EMNLP 2009 // AAAI 2008
All Publications
2026
 Universal NER v2: Towards a Massively Multilingual Named Entity Recognition Benchmark
LREC 2026
While multilingual language models promise to bring the benefits of LLMs to speakers of many languages, gold-standard evaluation benchmarks in most languages to interrogate these assumptions remain scarce. The Universal NER project, now entering its fourth year, is dedicated to building gold-standard multilingual Named Entity Recognition (NER) benchmark datasets. Inspired by existing massively multilingual efforts for other core NLP tasks (e.g., Universal Dependencies), the project uses a general tagset and thorough annotation guidelines to collect standardized, cross-lingual annotations of named entity spans. The first installment (UNER v1) was released in 2024, and the project has continued and expanded since then, with various organizers, annotators, and collaborators in an active community.
BibTeX
@inproceedings{terra2026universal,
  title={Universal NER v2: Towards a Massively Multilingual Named Entity Recognition Benchmark},
  author={Blevins, Terra and Mayhew, Stephen and Suppa, Marek and Gonen, Hila and Mirkin, Shachar and Pais, Vasile and Dobrovoljc, Kaja and Giouli, Voula and Kevin, Jun and Yılandiloğlu, Enes and Jang, Eugene and Kim, Eungseo and Seo, Jeongyeon and Gialis, Xenophon and Pinter, Yuval},
  year={2026},
  booktitle={LREC 2026},
  url={https://arxiv.org/abs/2604.12744}
}
2025
 All languages matter: Evaluating lmms on culturally diverse 100 languages
Proceedings of the Computer Vision and Pattern Recognition Conference , pp. 19565-19575
Existing Large Multimodal Models (LMMs) generally focus on only a few regions and languages. As LMMs continue to improve, it is increasingly important to ensure they understand cultural contexts, respect local sensitivities, and support low-resource languages, all while effectively integrating corresponding visual cues. In pursuit of culturally diverse global multimodal models, our proposed All Languages Matter Benchmark (ALM-bench) represents the largest and most comprehensive effort to date for evaluating LMMs across 100 languages. ALM-bench challenges existing models by testing their ability to understand and reason about culturally diverse images paired with text in various languages, including many low-resource languages traditionally underrepresented in LMM research. The benchmark offers a robust and nuanced evaluation framework featuring various question formats, including true/false, multiple choice, and open-ended questions, which are further divided into short and long-answer categories. ALM-bench design ensures a comprehensive assessment of a model’s ability to handle varied levels of difficulty in visual and linguistic reasoning. To capture the rich tapestry of global cultures, ALM-bench carefully curates content from 13 distinct cultural aspects, ranging from traditions and rituals to famous personalities and celebrations. Through this, ALM-bench not only provides a rigorous testing ground for state-of-the-art open and closed-source LMMs but also highlights the importance of cultural and linguistic inclusivity, encouraging the development of models that can serve diverse global populations effectively. Our benchmark is publicly available at https://mbzuai-oryx.github.io/ALM-Bench/.
BibTeX
@inproceedings{ashmal2025all,
  title={All languages matter: Evaluating lmms on culturally diverse 100 languages},
  author={Vayani, Ashmal and Dissanayake, Dinura and Watawana, Hasindri and Ahsan, Noor and Sasikumar, Nevasini and Thawakar, Omkar and Ademtew, Henok Biadglign and Hmaiti, Yahya and Kumar, Amandeep and Kuckreja, Kartik and Maslych, Mykola and Al Ghallabi, Wafa and Mihaylov, Mihail Minkov and Qin, Chao and Shaker, Abdelrahman M and Zhang, Mike and Ihsani, Mahardika Krisna and Esplana, Amiel Gian and Gokani, Monil and Mirkin, Shachar and Singh, Harsh and Srivastava, Ashay and Hamerlik, Endre and Izzati, Fathinah Asma and Maani, Fadillah Adamsyah and Cavada, Sebastian and Chim, Jenny and Gupta, Rohit and Manjunath, Sanjay and Zhumakhanova, Kamila and Rabevohitra, Feno Heriniaina and Amirudin, Azril Hafizi and Ridzuan, Muhammad and Abdul Kareem, Daniya Najiha and More, Ketan Pravin and Li, Kunyang and Shakya, Pramesh and Saad, Muhammad and Ghasemaghaei, Amirpouya and Djanibekov, Amirbek and Azizov, Dilshod and Jankovic, Branislava and Bhatia, Naman and Cabrera, Alvaro and Obando-Ceron, Johan and Otieno, Olympiah and Farestam, Febian and Rabbani, Muztoba and Ballah, Sanoojan and Sanjeev, Santosh and Shtanchaev, Abduragim and Fatima, Maheen and Nguyen, Thao and Kareem, Amrin and Aremu, Toluwani and Xavier, Nathan Augusto Zacarias and Bhatkal, Amit and Toyin, Hawau Olamide and Chadha, Aman and Cholakkal, Hisham and Anwer, Rao Muhammad and Felsberg, Michael and Laaksonen, Jorma and Solorio, Thamar and Choudhury, Monojit and Laptev, Ivan and Shah, Mubarak and Khan, Salman and Khan, Fahad Shahbaz},
  year={2025},
  booktitle={Proceedings of the Computer Vision and Pattern Recognition Conference},
  pages={19565-19575},
  url={https://openaccess.thecvf.com/content/CVPR2025/html/Vayani_All_Languages_Matter_Evaluating_LMMs_on_Culturally_Diverse_100_Languages_CVPR_2025_paper.html}
}
2022
 Bloom: A 176b-parameter open-access multilingual language model
arXiv preprint arXiv:2211.05100
Large language models (LLMs) have been shown to be able to perform new tasks based on a few demonstrations or natural language instructions. While these capabilities have led to widespread adoption, most LLMs are developed by resource-rich organizations and are frequently kept from the public. As a step towards democratizing this powerful technology, we present BLOOM, a 176B-parameter open-access language model designed and built thanks to a collaboration of hundreds of researchers. BLOOM is a decoder-only Transformer language model that was trained on the ROOTS corpus, a dataset comprising hundreds of sources in 46 natural and 13 programming languages (59 in total). We find that BLOOM achieves competitive performance on a wide variety of benchmarks, with stronger results after undergoing multitask prompted finetuning. To facilitate future research and applications using LLMs, we publicly release our models and code under the Responsible AI License.
BibTeX
@inproceedings{tevenle2022bloom,
  title={Bloom: A 176b-parameter open-access multilingual language model},
  author={Scao, Teven Le and Fan, Angela and Akiki, Christopher and Pavlick, Ellie and Ilić, Suzana and Hesslow, Daniel and Castagné, Roman and Luccioni, Alexandra Sasha and Yvon, François and Gallé, Matthias},
  year={2022},
  booktitle={arXiv preprint arXiv:2211.05100},
  url={https://arxiv.org/abs/2211.05100}
}
 Emergent Structures and Training Dynamics in Large Language Models
Challenges & Perspectives in Creating Large Language Models
Ryan Teehan, Miruna Clinciu, Oleg Serikov, Eliza Szczechla, Natasha Seelam, Shachar Mirkin, Aaron Gokaslan. Proceedings of BigScience Episode #5 -- Workshop on Challenges & Perspectives in Creating Large Language Models. 2022.
BibTeX
@inproceedings{ryan2022emergent,
  title={Emergent Structures and Training Dynamics in Large Language Models},
  author={Teehan, Ryan and Clinciu, Miruna and Serikov, Oleg and Szczechla, Eliza and Seelam, Natasha and Mirkin, Shachar and Gokaslan, Aaron},
  year={2022},
  booktitle={Challenges & Perspectives in Creating Large Language Models},
  url={https://aclanthology.org/2022.bigscience-1.11/}
}
2021
An autonomous debating system
Nature , Volume 591 (7850) , pp. 379-384
Artificial intelligence (AI) is defined as the ability of machines to perform tasks that are usually associated with intelligent beings. Argument and debate are fundamental capabilities of human intelligence, essential for a wide range of human activities, and common to all human societies. The development of computational argumentation technologies is therefore an important emerging discipline in AI research. Here we present Project Debater, an autonomous debating system that can engage in a competitive debate with humans. We provide a complete description of the system's architecture, a thorough and systematic evaluation of its operation across a wide range of debate topics, and a detailed account of the system's performance in its public debut against three expert human debaters. We also highlight the fundamental differences between debating with humans as opposed to challenging humans in game competitions, the latter being the focus of classical 'grand challenges' pursued by the AI research community over the past few decades. We suggest that such challenges lie in the 'comfort zone' of AI, whereas debating with humans lies in a different territory, in which humans still prevail, and for which novel paradigms are required to make substantial progress.
BibTeX
@article{slonim2021autonomous,
  title={An autonomous debating system},
  author={Slonim, Noam and Bilu, Yonatan and Alzate, Carlos and Bar-Haim, Roy and Bogin, Ben and Bonin, Francesca and Choshen, Leshem and Cohen-Karlik, Edo and Dankin, Lena and Edelstein, Lilach and others},
  journal={Nature},
  volume={591},
  number={7850},
  pages={379--384},
  year={2021},
  publisher={Nature Publishing Group UK London},
  doi={10.1038/s41586-021-03215-w}
}
2019
 A Dataset of General-Purpose Rebuttal
Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP)
Matan Orbach, Yonatan Bilu, Ariel Gera, Yoav Kantor, Lena Dankin, Tamar Lavee, Lili Kotlerman, Shachar Mirkin, Michal Jacovi, Ranit Aharonov, Noam Slonim. Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP). 2019.
BibTeX
@inproceedings{matan2019a,
  title={A Dataset of General-Purpose Rebuttal},
  author={Orbach, Matan and Bilu, Yonatan and Gera, Ariel and Kantor, Yoav and Dankin, Lena and Lavee, Tamar and Kotlerman, Lili and Mirkin, Shachar and Jacovi, Michal and Aharonov, Ranit},
  year={2019},
  booktitle={Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP)},
  url={https://aclanthology.org/D19-1561/}
}
 Towards effective rebuttal: Listening comprehension using corpus-wide claim mining
Proceedings of the 6th Workshop on Argument Mining , pp. 58-66
Engaging in a live debate requires, among other things, the ability to effectively rebut arguments claimed by your opponent. In particular, this requires identifying these arguments. Here, we suggest doing so by automatically mining claims from a corpus of news articles containing billions of sentences, and searching for them in a given speech. This raises the question of whether such claims indeed correspond to those made in spoken speeches. To this end, we collected a large dataset of $400$ speeches in English discussing $200$ controversial topics, mined claims for each topic, and asked annotators to identify the mined claims mentioned in each speech. Results show that in the vast majority of speeches debaters indeed make use of such claims. In addition, we present several baselines for the automatic detection of mined claims in speeches, forming the basis for future work. All collected data is freely available for research.
BibTeX
@inproceedings{tamar2019towards,
  title={Towards effective rebuttal: Listening comprehension using corpus-wide claim mining},
  author={Lavee, Tamar and Orbach, Matan and Kotlerman, Lili and Kantor, Yoav and Gretz, Shai and Dankin, Lena and Mirkin, Shachar and Jacovi, Michal and Bilu, Yonatan and Aharonov, Ranit},
  year={2019},
  booktitle={Proceedings of the 6th Workshop on Argument Mining},
  pages={58-66}
}
2018
 Listening comprehension over argumentative content
Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing , pp. 719-724
Shachar Mirkin, Guy Moshkowich, Matan Orbach, Lili Kotlerman, Yoav Kantor, Tamar Lavee, Michal Jacovi, Yonatan Bilu, Ranit Aharonov, Noam Slonim. Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing. 2018.
BibTeX
@inproceedings{shachar2018listening,
  title={Listening comprehension over argumentative content},
  author={Mirkin, Shachar and Moshkowich, Guy and Orbach, Matan and Kotlerman, Lili and Kantor, Yoav and Lavee, Tamar and Jacovi, Michal and Bilu, Yonatan and Aharonov, Ranit and Slonim, Noam},
  year={2018},
  booktitle={Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing},
  pages={719-724},
  url={https://aclanthology.org/D18-1078/}
}
 What did you mention? a large scale mention detection benchmark for spoken and written text
arXiv preprint arXiv:1801.07507
We describe a large, high-quality benchmark for the evaluation of Mention Detection tools. The benchmark contains annotations of both named entities as well as other types of entities, annotated on different types of text, ranging from clean text taken from Wikipedia, to noisy spoken data. The benchmark was built through a highly controlled crowd sourcing process to ensure its quality. We describe the benchmark, the process and the guidelines that were used to build it. We then demonstrate the results of a state-of-the-art system running on that benchmark.
BibTeX
@inproceedings{yosi2018what,
  title={What did you mention? a large scale mention detection benchmark for spoken and written text},
  author={Mass, Yosi and Kotlerman, Lili and Mirkin, Shachar and Venezian, Elad and Witzling, Gera and Slonim, Noam},
  year={2018},
  booktitle={arXiv preprint arXiv:1801.07507}
}
 A recorded debating dataset
Proceedings of the Eleventh International Conference on Language Resources and Evaluation (LREC 2018)
This paper describes an English audio and textual dataset of debating speeches, a unique resource for the growing research field of computational argumentation and debating technologies. We detail the process of speech recording by professional debaters, the transcription of the speeches with an Automatic Speech Recognition (ASR) system, their consequent automatic processing to produce a text that is more "NLP-friendly", and in parallel -- the manual transcription of the speeches in order to produce gold-standard "reference" transcripts. We release 60 speeches on various controversial topics, each in five formats corresponding to the different stages in the production of the data. The intention is to allow utilizing this resource for multiple research purposes, be it the addition of in-domain training data for a debate-specific ASR system, or applying argumentation mining on either noisy or clean debate transcripts. We intend to make further releases of this data in the future.
BibTeX
@inproceedings{shachar2018a,
  title={A recorded debating dataset},
  author={Mirkin, Shachar and Jacovi, Michal and Lavee, Tamar and Kuo, Hong-Kwang and Thomas, Samuel and Sager, Leslie and Kotlerman, Lili and Venezian, Elad and Slonim, Noam},
  year={2018},
  booktitle={Proceedings of the Eleventh International Conference on Language Resources and Evaluation (LREC 2018)},
  url={https://aclanthology.org/L18-1037/}
}
 System and method for predicting an optimal machine translation system for a user based on an updated user profile
A method for identifying an optimal machine translation system for a user using a collaborative filtering approach. The system maintains user profiles containing pairwise rankings of various translation systems. To predict the best system for a specific user, it identifies nearest neighbors who share similar translation preferences based on existing rankings. If data is missing for a user, the system fills these gaps by computing weighted averages of the rankings provided by these nearest neighbors. This updated profile then determines the optimal translation system to use, providing personalized machine translation recommendations.
BibTeX
@misc{mirkin2018system,
  title={System and method for predicting an optimal machine translation system for a user based on an updated user profile},
  author={Mirkin, Shachar and Meunier, Jean-Luc},
  year={2018},
  note={US Patent 10,025,779},
  url={https://patents.google.com/patent/US10025779}
}
2017
 Joint Learning of Correlated Sequence Labelling Tasks Using Bidirectional Recurrent Neural Networks
Interspeech 2017
The stream of words produced by Automatic Speech Recognition (ASR) systems is typically devoid of punctuations and formatting. Most natural language processing applications expect segmented and well-formatted texts as input, which is not available in ASR output. This paper proposes a novel technique of jointly modeling multiple correlated tasks such as punctuation and capitalization using bidirectional recurrent neural networks, which leads to improved performance for each of these tasks. This method could be extended for joint modeling of any other correlated sequence labeling tasks.
BibTeX
@inproceedings{vardaan2017joint,
  title={Joint Learning of Correlated Sequence Labelling Tasks Using Bidirectional Recurrent Neural Networks},
  author={Pahuja, Vardaan and Laha, Anirban and Mirkin, Shachar and Raykar, Vikas and Kotlerman, Lili and Lev, Guy},
  year={2017},
  booktitle={Interspeech 2017}
}
 Personalized Machine Translation: Preserving Original Author Traits
EACL 2017
The language that we produce reflects our personality, and various personal and demographic characteristics can be detected in natural language texts. We focus on one particular personal trait of the author, gender, and study how it is manifested in original texts and in translations. We show that author’s gender has a powerful, clear signal in originals texts, but this signal is obfuscated in human and machine translation. We then propose simple domain-adaptation techniques that help retain the original gender traits in the translation, without harming the quality of the translation, thereby creating more personalized machine translation systems.
BibTeX
@inproceedings{ella2017personalized,
  title={Personalized Machine Translation: Preserving Original Author Traits},
  author={Rabinovich, Ella and Mirkin, Shachar and Patel, Raj Nath and Specia, Lucia and Wintner, Shuly},
  year={2017},
  booktitle={EACL 2017},
  url={https://aclanthology.org/E17-1101/}
}
2016
 Learning generation templates from dialog transcripts
A system for generating agent responses in call centers using weighted finite state automata (WFSA). The system constructs word lattices from training dialogs by clustering agent utterances based on preceding customer context and grammatical dependency features. These lattices are assigned conditional probabilities relative to specific dialog acts, which are then used to rank, select, and instantiate the most relevant utterance patterns. This approach enables the generation of fluent, contextually appropriate responses to dialog acts recommended by a dialog manager.
BibTeX
@misc{venkatapathy2016learning,
  title={Learning generation templates from dialog transcripts},
  author={Venkatapathy, Sriram and Mirkin, Shachar and Dymetman, Marc},
  year={2016},
  note={US Patent 9,473,637},
  url={https://patents.google.com/patent/US9473637}
}
 Method and system for summarizing a document
A method and system for summarizing an electronic document using natural language processing and graph-based algorithms. The method extracts sentences from the document, creates a graph with nodes representing sentences, and places edges between sentence pairs based on entailment scores. A minimum vertex cover algorithm is applied to the graph to identify an optimal set of sentences for the summary. This approach leverages textual entailment to model sentence connectivity and produces summaries that capture the key information in the document.
BibTeX
@misc{gupta2016method,
  title={Method and system for summarizing a document},
  author={Gupta, Anand and Kaur, Manpreet and Mirkin, Shachar},
  year={2016},
  note={US Patent App. 14/680,096},
  url={https://patents.google.com/patent/US20160299881}
}
 System and method for incrementally updating a reordering model for a statistical machine translation system
A method for incrementally updating a reordering model in a statistical machine translation system. The process involves extracting phrase pairs from new training data to generate a new reordering file, then merging this with existing data to update the model. This approach allows for faster, more frequent updates compared to retraining from scratch, enabling the SMT system to be kept up-to-date with the most recent data. The system uses an RM update component to generate an updated reordering table while maintaining feature scores for orientation types and incorporating new counts.
BibTeX
@misc{mirkin2016system,
  title={System and method for incrementally updating a reordering model for a statistical machine translation system},
  author={Mirkin, Shachar},
  year={2016},
  note={US Patent 9,442,922},
  url={https://patents.google.com/patent/US9442922}
}
2015
 Motivating Personality-aware Machine Translation
The 2015 Conference on Empirical Methods on Natural Language Processing (EMNLP)
Language use is known to be influenced by personality traits as well as by sociodemographic characteristics such as age or mother tongue.As a result, it is possible to automatically identify these traits of the author from her texts.It has recently been shown that knowledge of such dimensions can improve performance in NLP tasks such as topic and sentiment modeling.We posit that machine translation is another application that should be personalized.In order to motivate this, we explore whether translation preserves demographic and psychometric traits.We show that, largely, both translation of the source training data into the target language, and the target test data into the source language has a detrimental effect on the accuracy of predicting author traits.We argue that this supports the need for personal and personality-aware machine translation models.
BibTeX
@inproceedings{shachar2015motivating,
  title={Motivating Personality-aware Machine Translation},
  author={Mirkin, Shachar and Nowson, Scott and Brun, Caroline and Perez, Julien},
  year={2015},
  booktitle={The 2015 Conference on Empirical Methods on Natural Language Processing (EMNLP)},
  url={https://aclanthology.org/D15-1130/}
}
 Personalized machine translation: Predicting translational preferences
Proceedings of the 2015 conference on empirical methods in natural language processing , pp. 2019-2025
Machine Translation (MT) has advanced in recent years to produce better translations for clients' specific domains, and sophisticated tools allow professional translators to obtain translations according to their prior edits. We suggest that MT should be further personalized to the end-user level -the receiver or the author of the text -as done in other applications. As a step in that direction, we propose a method based on a recommender systems approach where the user's preferred translation is predicted based on preferences of similar users. In our experiments, this method outperforms a set of non-personalized methods, suggesting that user preference information can be employed to provide better-suited translations for each user.
BibTeX
@inproceedings{shachar2015personalized,
  title={Personalized machine translation: Predicting translational preferences},
  author={Mirkin, Shachar and Meunier, Jean-Luc},
  year={2015},
  booktitle={Proceedings of the 2015 conference on empirical methods in natural language processing},
  pages={2019-2025},
  url={https://aclanthology.org/D15-1238/}
}
 XRCE personal language analytics engine for multilingual author profiling
Working Notes Papers of the CLEF , pp. 1412-1424
This technical notebook describes the methodology used - and results achieved - for the PAN 2015 Author Profiling Challenge by the team from Xe- rox Research Centre Europe (XRCE). This year, personality traits are introduced alongside age and gender in a corpus of tweets in four languages - English, Span- ish, Italian and Dutch. We describe a largely language agnostic methodology for classification which uses language specific linguistic processing to generate fea- tures. We also report on experiments in which we use machine translation to accommodate for languages in which there is less training data. Native language results are successful, but socio-demographic signals in language seem to be lost under MT conditions.
BibTeX
@inproceedings{scott2015xrce,
  title={XRCE personal language analytics engine for multilingual author profiling},
  author={Nowson, Scott and Perez, Julien and Brun, Caroline and Mirkin, Shachar and Roux, Claude},
  year={2015},
  booktitle={Working Notes Papers of the CLEF},
  pages={1412-1424}
}
 Semantic refining of cross-lingual information retrieval results
A method for cross-language information retrieval that receives an input query in a source language, translates it to a target language, retrieves documents from a document collection, translates the retrieved documents back into the source language, and assesses entailment relationships between the translated documents and the input query. The set of translated documents is refined based on the assessment of the entailment relationship, improving the quality of cross-lingual search results by filtering out documents that do not truly match the query intent.
BibTeX
@misc{mirkin2015semantic,
  title={Semantic refining of cross-lingual information retrieval results},
  author={Mirkin, Shachar and Lagos, Nikolaos and Calapodescu, Ioan},
  year={2015},
  note={US Patent App. 14/276,252},
  url={https://patents.google.com/patent/US20150199339}
}
 Refining inference rules with temporal event clustering
A method for computing similarity between paths by extracting triples from a text corpus, clustering documents based on textual and temporal similarity, and calculating similarity scores using both corpus statistics and cluster-based predicate occurrences. The process enables generating inference rules when computed event-based path similarity meets a predefined threshold. This approach improves semantic inference by leveraging the temporal relationships between events in document collections.
BibTeX
@misc{jacquet2015refining,
  title={Refining inference rules with temporal event clustering},
  author={Jacquet, Guillaume and Mirkin, Shachar},
  year={2015},
  note={US Patent App. 14/070,786},
  url={https://patents.google.com/patent/US20150127323}
}
 Machine translation-driven authoring system and method
An authoring system assists users in composing source language text by providing real-time suggestions to improve translatability into a target language. The system uses a suggestion model that evaluates candidate phrases based on translatability scores derived from statistical machine translation biphrase tables. The process is iterative users select suggested completions to build the source text, which is then translated by an SMT decoder. This technology enables monolinguals to author texts that can be reliably translated without requiring post-editing by bilinguals.
BibTeX
@misc{venkatapathy2015machine,
  title={Machine translation-driven authoring system and method},
  author={Venkatapathy, Sriram and Mirkin, Shachar},
  year={2015},
  note={US Patent 9,047,274},
  url={https://patents.google.com/patent/US9047274}
}
2014
 Confidence-driven rewriting of source texts for improved translation
A method and system for improving machine translation quality by automatically rewriting source sentences using confidence estimation. The system identifies sentences likely to be poorly translated and suggests alternative phrasings to a monolingual user. Source modifications are induced by confidence estimates derived from the translation model in use. Modifications are automatically generated and proposed for the user's approval. This approach reduces post-editing effort by replacing it with cost-effective pre-editing that can be performed by monolinguals.
BibTeX
@misc{mirkin2014confidence,
  title={Confidence-driven rewriting of source texts for improved translation},
  author={Mirkin, Shachar and Venkatapathy, Sriram and Dymetman, Marc},
  year={2014},
  note={US Patent App. 13/908,157},
  url={https://patents.google.com/patent/US20140358519}
}
 Incrementally Updating the SMT Reordering Model
Proceedings of The 28th Pacific Asia Conference on Language, Information and Computing (PACLIC), Phuket, Thailand
This work is concerned with incrementally training statistical machine translation (SMT) models when new data becomes available.That, in contrast to re-training new models based on the entire accumulated data.Incremental training provides a way to perform faster, more frequent model updates, enabling keeping the SMT system up-to-date with the most recent data.Specifically, we address incrementally updating the reordering model (RM), a component in phrase-based machine translation that models phrase order changes between the source and the target languages, and for which incremental training has not been proposed so far.First, we show that updating the reordering model is helpful for improving translation quality.Second, we present an algorithm for updating the reordering model within the popular Moses SMT system.Our method produces the exact same model as when training the model from scratch, but doing so much faster.
BibTeX
@inproceedings{shachar2014incrementally,
  title={Incrementally Updating the SMT Reordering Model},
  author={Mirkin, Shachar},
  year={2014},
  booktitle={Proceedings of The 28th Pacific Asia Conference on Language, Information and Computing (PACLIC), Phuket, Thailand},
  url={https://aclanthology.org/Y14-1033/}
}
 Comparison of data selection techniques for the translation of video lectures
For the task of online translation of scientific video lectures, using huge models is not possi-ble. In order to get smaller and efficient models, we perform data selection. In this paper, we perform a qualitative and quantitative comparison of several data selection techniques, based on cross-entropy and infrequent n-gram criteria. In terms of BLEU, a combination of transla-tion and language model cross-entropy achieves the most stable results. As another important criterion for measuring translation quality in our application, we identify the number of out-of-vocabulary words. Here, infrequent n-gram recovery shows superior performance. Finally, we combine the two selection techniques in order to benefit from both their strengths.
BibTeX
@inproceedings{joern2014comparison,
  title={Comparison of data selection techniques for the translation of video lectures},
  author={Wuebker, Joern and Ney, Hermann and Martínez-Villaronga, Adrià and Giménez Pastor, Adrián and Juan Císcar, Alfonso and Servan, Christophe and Dymetman, Marc and Mirkin, Shachar},
  year={2014},
  organization={Association for Machine Translation in the Americas},
  url={https://aclanthology.org/2014.amta-researchers.15/}
}
 Data Selection for Compact Adapted SMT Models
Proceedings of AMTA
Data selection is a common technique for adapting statistical translation models for a specific domain, which has been shown to both improve translation quality and to reduce model size. Selection relies on some in-domain data, of the same domain of the texts expected to be trans-lated. Selecting the sentence-pairs that are most similar to the in-domain data from a pool of parallel texts has been shown to be effective; yet, this approach holds the risk of resulting in a limited coverage, when necessary n-grams that do appear in the pool are less similar to in-domain data that is available in advance. Some methods select additional data based on the actual text that needs to be translated. While useful, this is not always a practical scenario. In this work we describe an extensive exploration of data selection techniques over Arabic to French datasets, and propose methods to address both similarity and coverage considerations while maintaining a limited model size.
BibTeX
@inproceedings{shachar2014data,
  title={Data Selection for Compact Adapted SMT Models},
  author={Mirkin, Shachar and Besacier, Laurent},
  year={2014},
  booktitle={Proceedings of AMTA},
  url={https://aclanthology.org/2014.amta-researchers.23/}
}
 Text summarization through entailment-based minimum vertex cover
Proceedings of the Third Joint Conference on Lexical and Computational Semantics (* SEM 2014) , pp. 75-80
Sentence Connectivity is a textual characteristic that may be incorporated intelligently for the selection of sentences of a well meaning summary. However, the existing summarization methods do not utilize its potential fully. The present paper introduces a novel method for singledocument text summarization. It poses the text summarization task as an optimization problem, and attempts to solve it using Weighted Minimum Vertex Cover (WMVC), a graph-based algorithm. Textual entailment, an established indicator of semantic relationships between text units, is used to measure sentence connectivity and construct the graph on which WMVC operates. Experiments on a standard summarization dataset show that the suggested algorithm outperforms related methods.
BibTeX
@inproceedings{anand2014text,
  title={Text summarization through entailment-based minimum vertex cover},
  author={Gupta, Anand and Kaur, Manpreet and Mirkin, Shachar and Singh, Adarsh and Goyal, Aseem},
  year={2014},
  booktitle={Proceedings of the Third Joint Conference on Lexical and Computational Semantics (* SEM 2014)},
  pages={75-80},
  url={https://aclanthology.org/S14-1010/}
}
2013
 Confidence-driven Rewriting for Improved Translation
MT Summit
Some source texts are more difficult to translate than others. One way to handle such texts is to modify them prior to translation. Yet, a prominent factor that is often overlooked is the source translatability with respect to the specific translation system and the specific model that are being used. We present an approach, and an interactive tool implementing it, where source sentences are rewritten in order to maximize confidence estimates with respect to the translation model. The automatically-generated rewritings are then proposed for the user's approval. Such an approach can reduce post-editing effort, replacing it by cost-effective pre-editing that can be done by monolinguals.
BibTeX
@inproceedings{mirkin2013confidence,
  title={Confidence-driven Rewriting for Improved Translation},
  author={Mirkin, Shachar and Venkatapathy, Sriram and Dymetman, Marc},
  booktitle={Proceedings of MT Summit XIV},
  year={2013},
  url={https://aclanthology.org/2013.mtsummit-posters.8/}
}
 Assessing quick update methods of statistical translation models
Proceedings of the International Workshop of Spoken Language Translation (IWSLT) , pp. 264-271
International audience
BibTeX
@inproceedings{shachar2013assessing,
  title={Assessing quick update methods of statistical translation models},
  author={Mirkin, Shachar and Cancedda, Nicola},
  year={2013},
  booktitle={Proceedings of the International Workshop of Spoken Language Translation (IWSLT)},
  pages={264-271},
  url={https://aclanthology.org/2013.iwslt-papers.10/}
}
 Error prediction with partial feedback
Machine Learning and Knowledge Discovery in Databases: European Conference, ECML PKDD 2013, Prague, Czech Republic, September 23-27, 2013, Proceedings, Part II 13 , pp. 80-94
In this paper, we propose a probabilistic framework for predicting the root causes of errors in data processing pipelines made up of several components when we only have access to partial feedback; that is, we are aware when some error has occurred in one or more of the components, but we do not know which one. The proposed error model enables us to direct the user feedback to the correct components in the pipeline to either automatically correct errors as they occur, retrain the component with assimilated training examples, or take other corrective action. We present the model and describe an Expectation Maximization (EM)-based algorithm to learn the model parameters and predict the error configuration. We demonstrate the accuracy and usefulness of our method first on synthetic data, and then on two distinct tasks error correction in a 2-component opinion summarization system, and phrase error detection in statistical machine translation.
BibTeX
@inproceedings{darling2013error,
  title={Error Prediction with Partial Feedback},
  author={Darling, William and Archambeau, C{\'e}dric and Mirkin, Shachar and Bouchard, Guillaume},
  booktitle={European Conference on Machine Learning and Principles and Practice of Knowledge Discovery in Databases},
  pages={80--94},
  year={2013},
  publisher={Springer Berlin Heidelberg},
  doi={10.1007/978-3-642-40991-2_6}
}
 SORT: An Interactive Source-Rewriting Tool for Improved Translation
ACL Demos
The quality of automatic translation is affected by many factors. One is the divergence between the specific source and target languages. Another lies in the source text itself, as some texts are more complex than others. One way to handle such texts is to modify them prior to translation. Yet, an important factor that is often overlooked is the source translatability with respect to the specific translation system and the specific model that are being used. In this paper we present an interactive system where source modifications are induced by confidence estimates that are derived from the translation model in use. Modifications are automatically generated and proposed for the user’s approval. Such a system can reduce postediting effort, replacing it by cost-effective pre-editing that can be done by monolinguals.
BibTeX
@inproceedings{shachar2013sort,
  title={SORT: An Interactive Source-Rewriting Tool for Improved Translation},
  author={Mirkin, Shachar and Venkatapathy, Sriram and Dymetman, Marc and Calapodescu, Ioan},
  year={2013},
  booktitle={ACL Demos},
  url={https://aclanthology.org/P13-4015/}
}
2012
 An SMT-driven authoring tool
Proceedings of COLING 2012: Demonstration Papers , pp. 459-466
This paper presents a tool for assisting users in composing texts in a language they do not know. While Machine Translation (MT) is pretty useful for understanding texts in an unfamiliar language, current MT technology has yet to reach the stage where it can be used reliably without a post-editing step. This work attempts to make a step towards achieving this goal. We propose a tool that provides suggestions for the continuation of the text in the source language (that the user knows), creating texts that can be translated to the target language (that the user does not know). In terms of functionality, our tool resembles text prediction applications. However , the target language, through a Statistical Machine Translation (SMT) model, drives the composition and not only the source language. We present the user interface and describe the considerations that underline the suggestion process. A simulation of user interaction shows that composition speed can be substantially reduced and provides initial positive feedback as to the ability to generate better translations.
BibTeX
@inproceedings{sriram2012an,
  title={An SMT-driven authoring tool},
  author={Venkatapathy, Sriram and Mirkin, Shachar},
  year={2012},
  booktitle={Proceedings of COLING 2012: Demonstration Papers},
  pages={459-466},
  url={https://aclanthology.org/C12-3058/}
}
2011
 Context and Discourse in Textual Entailment Inference
PhD Thesis
This thesis addresses applied semantic inference within the Textual Entailment framework, focusing on context and discourse aspects of inference. It demonstrates that standard textual entailment systems rely too heavily on limited coreference resolution, and shows that incorporating broader discourse phenomena, such as bridging relations and verbal references, significantly improves entailment performance. The work explores using discourse references to complement existing entailment knowledge and rules, providing empirical evidence that discourse provides useful information for improved inference systems.
BibTeX
@phdthesis{mirkin2011context,
  title={Context and Discourse in Textual Entailment Inference},
  author={Mirkin, Shachar},
  year={2011},
  school={Bar-Ilan University},
  url={https://shacharmirkin.github.io/assets/papers/mirkin-2011-phd-thesis-context-discourse-textual-entailment.pdf}
}
 Knowledge and Tree-Edits in Learnable Entailment Proofs
TAC
This paper describes BIUTEE - Bar Ilan University Textual Entailment Engine. BIUTEE is a natural language inference system in which the hypothesis is proven by the text, based on linguistic- and world- knowledge resources, as well as syntactically motivated tree transformations. The main progress in BIUTEE in the last year is a new confidence model that estimates the validity of the proof found by BIUTEE.
BibTeX
@inproceedings{asher2011knowledge,
  title={Knowledge and Tree-Edits in Learnable Entailment Proofs},
  author={Stern, Asher and Mirkin, Shachar and Shnarch, Eyal and Kotlerman, Lili and Dagan, Ido and Lotan, Amnon and Berant, Jonathan},
  year={2011},
  booktitle={TAC}
}
 Classification-based contextual preferences
Proceedings of the TextInfer 2011 Workshop on Textual Entailment , pp. 20-29
This paper addresses context matching in tex-tual inference. We formulate the task under the Contextual Preferences framework which broadly captures contextual aspects of infer-ence. We propose a generic classification-based scheme under this framework which co-herently attends to context matching in infer-ence and may be employed in any inference-based task. As a test bed for our scheme we use the Name-based Text Categorization (TC) task. We define an integration of Contextual Prefer-ences into the TC setting and present a concrete self-supervised model which instantiates the generic scheme and is applied to address con-text matching in the TC task. Experiments on standard TC datasets show that our approach outperforms the state of the art in context mod-eling for Name-based TC.
BibTeX
@inproceedings{shachar2011classification,
  title={Classification-based contextual preferences},
  author={Mirkin, Shachar and Dagan, Ido and Kotlerman, Lili and Szpektor, Idan},
  year={2011},
  booktitle={Proceedings of the TextInfer 2011 Workshop on Textual Entailment},
  pages={20-29},
  url={https://aclanthology.org/W11-2403/}
}
2010
 Rule Chaining and Approximate Match in textual inference
TAC
This paper describes the participation of Bar-Ilan university in the sixth RTE challenge. Our textual-entailment engine, BiuTee, was enhanced with new components that introduce chaining of lexical-entailment rules, and tackle the problem of approximately matching the text and the hypothesis after all available knowledge of entailment rules was utilized. We have also re-engineered our system aiming at an open-source open architecture. BiuTee’s performance is better than the median of all-submissions, and outperforms significantly an IR-oriented baseline.
BibTeX
@inproceedings{asher2010rule,
  title={Rule Chaining and Approximate Match in textual inference},
  author={Stern, Asher and Shnarch, Eyal and Mirkin, Shachar and Kotlerman, Lili and Zeichner, Naomi and Dagan, Ido and Lotan, Amnon and Berant, Jonathan},
  year={2010},
  booktitle={TAC}
}
 Learning an expert from human annotations in statistical machine translation: The case of out-of-vocabulary words
Proceedings of the 14th Annual Conference of the European Association for Machine Translation
We present a general method for incorporating an “expert ” model into a Statistical Machine Translation (SMT) system, in order to improve its performance on a particular “area of expertise”, and apply this method to the specific task of finding adequate replacements for Out-of-Vocabulary (OOV) words. Candidate replacements are paraphrases and entailed phrases, obtained using monolingual resources. These candidate replacements are transformed into “dynamic biphrases”, generated at decoding time based on the context of each source sentence. Standard SMT features are enhanced with a number of new features aimed at scoring translations produced by using different replacements. Active learning is used to discriminatively train the model parameters from human assessments of the quality of translations. The learning framework yields an SMT system which is able to deal with sentences containing OOV words but also guarantees that the performance is not degraded for input sentences without OOV words. Results of experiments on English-French translation show that this method outperforms previous work addressing OOV words in terms of acceptability.
BibTeX
@inproceedings{wilker2010learning,
  title={Learning an expert from human annotations in statistical machine translation: The case of out-of-vocabulary words},
  author={Aziz, Wilker and Dymetman, Marc and Specia, Lucia and Mirkin, Shachar},
  year={2010},
  booktitle={Proceedings of the 14th Annual Conference of the European Association for Machine Translation},
  url={https://aclanthology.org/2010.eamt-1.31/}
}
 Recognising entailment within discourse
Proceedings of the 23rd International Conference on Computational Linguistics , pp. 770-778
Texts are commonly interpreted based on the entire discourse in which they are situated. Discourse processing has been shown useful for inference-based application; yet, most systems for textual entailment – a generic paradigm for applied inference – have only addressed discourse considerations via off-the-shelf coreference resolvers. In this paper we explore various discourse aspects in entailment inference, suggest initial solutions for them and investigate their impact on entailment performance. Our experiments suggest that discourse provides useful information, which significantly improves entailment inference, and should be better addressed by future entailment systems.
BibTeX
@inproceedings{shachar2010recognising,
  title={Recognising entailment within discourse},
  author={Mirkin, Shachar and Berant, Jonathan and Dagan, Ido and Shnarch, Eyal},
  year={2010},
  booktitle={Proceedings of the 23rd International Conference on Computational Linguistics},
  pages={770-778},
  organization={Association for Computational Linguistics},
  url={https://aclanthology.org/C10-1087/}
}
 A Resource for Investigating the Impact of Anaphora and Coreference on Inference
LREC
Discourse phenomena play a major role in text processing tasks. However, so far relatively little study has been devoted to the relevance of discourse phenomena for inference. Therefore, an experimental study was carried out to assess the relevance of anaphora and coreference for Textual Entailment (TE), a prominent inference framework. First, the annotation of anaphoric and coreferential links in the RTE-5 Search data set was performed according to a specifically designed annotation scheme. As a result, a new data set was created where all anaphora and coreference instances in the entailing sentences which are relevant to the entailment judgment are solved and annotated. A by-product of the annotation is a new “augmented ” data set, where all the referring expressions which need to be resolved in the entailing sentences are replaced by explicit expressions. Starting from the final output of the annotation, the actual impact of discourse phenomena on inference engines was investigated, identifying the kind of operations that the systems need to apply to address discourse phenomena and trying to find direct mappings between these operation and annotation types.
BibTeX
@inproceedings{azad2010a,
  title={A Resource for Investigating the Impact of Anaphora and Coreference on Inference},
  author={Abad, Azad and Bentivogli, Luisa and Dagan, Ido and Giampiccolo, Danilo and Mirkin, Shachar and Pianta, Emanuele and Stern, Asher},
  year={2010},
  booktitle={LREC},
  url={https://aclanthology.org/L10-1338/}
}
 Assessing the role of discourse references in entailment inference
Proceedings of the 48th Annual Meeting of the Association for Computational Linguistics , pp. 1209-1219
Discourse references, notably coreference and bridging, play an important role in many text understanding applications, but their impact on textual entailment is yet to be systematically understood. On the ba-sis of an in-depth analysis of entailment instances, we argue that discourse refer-ences have the potential of substantially improving textual entailment recognition, and identify a number of research direc-tions towards this goal.
BibTeX
@inproceedings{shachar2010assessing,
  title={Assessing the role of discourse references in entailment inference},
  author={Mirkin, Shachar and Dagan, Ido and Padó, Sebastian},
  year={2010},
  booktitle={Proceedings of the 48th Annual Meeting of the Association for Computational Linguistics},
  pages={1209-1219},
  url={https://aclanthology.org/P10-1123/}
}
2009
 Addressing Discourse and Document Structure in the RTE Search Task
TAC
This paper describes Bar-Ilan University’s submissions to RTE-5. This year we focused on the Search pilot, enhancing our entailment system to address two main issues introduced by this new setting: scalability and, primarily, document-level discourse. Our system achieved the highest score on the Search task amongst participating groups, and proposes first steps towards addressing this challenging setting.
BibTeX
@inproceedings{shachar2009addressing,
  title={Addressing Discourse and Document Structure in the RTE Search Task},
  author={Mirkin, Shachar and Bar-Haim, Roy and Dagan, Ido and Shnarch, Eyal and Stern, Asher and Szpektor, Idan and Berant, Jonathan},
  year={2009},
  booktitle={TAC}
}
 Evaluating the inferential utility of lexical-semantic resources
Proceedings of the 12th Conference of the European Chapter of the ACL (EACL 2009) , pp. 558-566
Lexical-semantic resources are used extensively for applied semantic inference, yet a clear quantitative picture of their current utility and limitations is largely missing.
BibTeX
@inproceedings{shachar2009evaluating,
  title={Evaluating the inferential utility of lexical-semantic resources},
  author={Mirkin, Shachar and Dagan, Ido and Shnarch, Eyal},
  year={2009},
  booktitle={Proceedings of the 12th Conference of the European Chapter of the ACL (EACL 2009)},
  pages={558-566},
  url={https://aclanthology.org/E09-1064/}
}
 Source-language entailment modeling for translating unknown terms
Proceedings of the Joint Conference of the 47th Annual Meeting of the ACL and the 4th International Joint Conference on Natural Language Processing of the AFNLP , pp. 791-799
This paper addresses the task of handling unknown terms in SMT. We propose using source-language monolingual models and resources to paraphrase the source text prior to translation. We further present a conceptual extension to prior work by allowing translations of entailed texts rather than paraphrases only. A method for performing this process efficiently is presented and applied to some 2500 sentences with unknown terms. Our experiments show that the proposed approach substantially increases the number of properly translated texts.
BibTeX
@inproceedings{mirkin2009source,
  title={Source-language entailment modeling for translating unknown terms},
  author={Mirkin, Shachar and Specia, Lucia and Cancedda, Nicola and Dagan, Ido and Dymetman, Marc and Szpektor, Idan},
  booktitle={Proceedings of the Joint Conference of the 47th Annual Meeting of the ACL and the 4th International Joint Conference on Natural Language Processing of the AFNLP},
  pages={791--799},
  year={2009},
  url={https://aclanthology.org/P09-1089/}
}
2008
 Efficient semantic deduction and approximate matching over compact parse forests
Proceedings of TAC
Semantic inference is often modeled as application of entailment rules, which specify generation of entailed sentences from a source sentence. Efficient generation and representation of entailed consequents is a fundamental problem common to such inference methods. We present a new data structure, termed compact forest, which allows efficient generation and representation of entailed consequents, each represented as a parse tree. Rule-based inference is complemented with a new approximate matching measure inspired by tree kernels, which is computed efficiently over compact forests. Our system also makes use of novel large-scale entailment rule bases, derived from Wikipedia as well as from information about predicates and their argument mapping, gathered from available lexicons and complemented by unsupervised learning.
BibTeX
@inproceedings{barhaim2008efficient,
  title={Efficient semantic deduction and approximate matching over compact parse forests},
  author={Bar-Haim, Roy and Berant, Jonathan and Dagan, Ido and Greental, Iddo and Mirkin, Shachar and Shnarch, Eyal and Szpektor, Idan},
  booktitle={Proceedings of TAC},
  year={2008}
}
2006
 Integrating pattern-based and distributional similarity methods for lexical entailment acquisition
Proceedings of the COLING/ACL 2006 Main Conference Poster Sessions , pp. 579-586
This paper addresses the problem of acquiring lexical semantic relationships, applied to the lexical entailment relation. Our main contribution is a novel conceptual integration between the two distinct acquisition paradigms for lexical relations - the pattern-based and the distributional similarity approaches. The integrated method exploits mutual complementary information of the two approaches to obtain candidate relations and informative characterizing features. Then, a small size training set is used to construct a more accurate supervised classifier, showing significant increase in both recall and precision over the original approaches.
BibTeX
@inproceedings{shachar2006integrating,
  title={Integrating pattern-based and distributional similarity methods for lexical entailment acquisition},
  author={Mirkin, Shachar and Dagan, Ido and Geffet, Maayan},
  year={2006},
  booktitle={Proceedings of the COLING/ACL 2006 Main Conference Poster Sessions},
  pages={579-586},
  url={https://aclanthology.org/P06-2075/}
}